


Not just PlayStation 5Unexpectedly, even the PlayStation 4, which has been out for more than 10 years, can be turned into an AI server. Recently, a developer did just that and shared it on GitHub under the name Garlic LLM. Created by Leonardo Alegría, it lets the PS4 run Alibaba’s Qwen 3.5-9B model with 9 billion parameters directly on the console. The entire process is completely offline and does not require connecting to another computer, with text generation speeds of up to 43 Tokens per second.
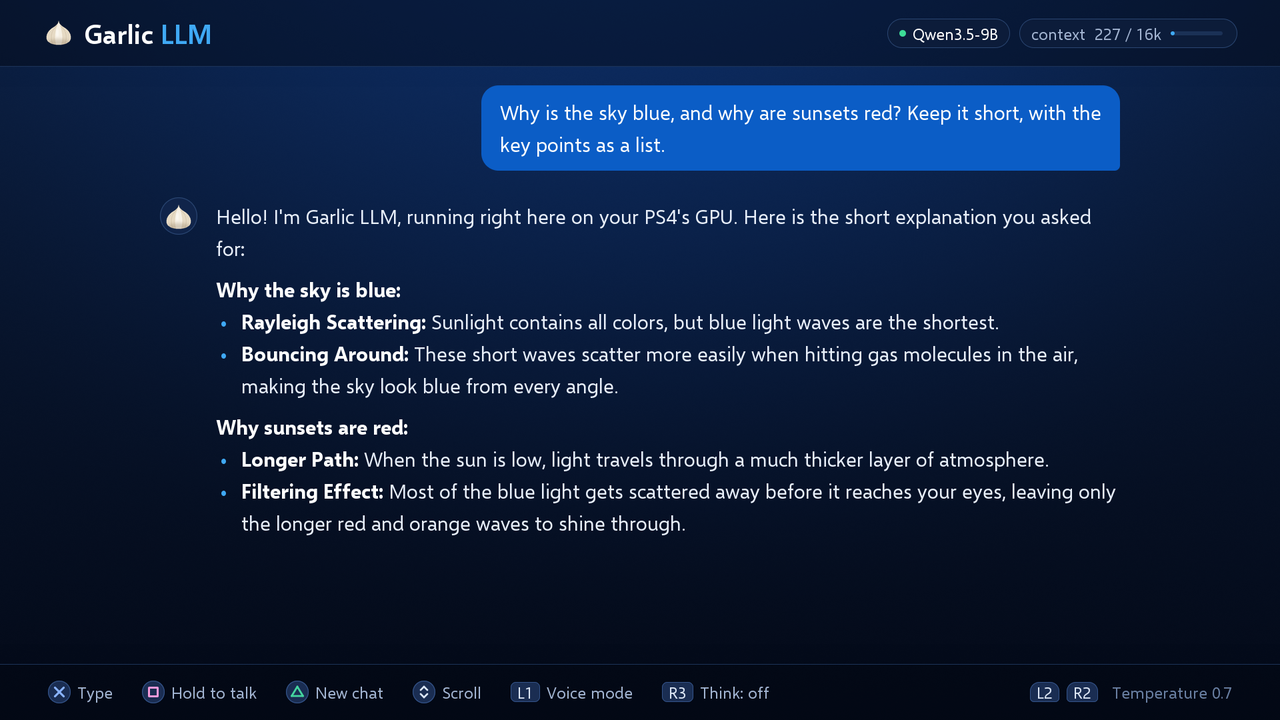
Image source: Garlic LLM
A 13-year-old PS4 can run AI too! Open-source Garlic LLM lets jailbroken consoles run a 9-billion-parameter model offline at up to 43 tokens per second.
According to foreign media Tom’s Hardware According to reports, there has appeared on GitHub a Garlic LLM The project is AI software designed specifically for the PS4, with Alibaba’s open-weight model Qwen3.5-9B released this year built in, and all computation handled through the PS4’s GPU. According to data published by the developer on GitHub, on the original and Slim PS4 models, general text chat speeds range from 31 to 39 tokens per second, and reach up to 43 tokens per second when generating code; switching to voice conversation mode drops it to about 22 tokens per second.
However, it is worth noting that these speed figures all come from the developers themselves, with no explanation of the prompts used for testing or the measurement method, and they are not yet independent, standardized performance tests, so they should be treated as reference only.
Image source: Garlic LLM
The PS4 only has 8GB of GDDR5 memory and uses a unified memory architecture shared by the CPU and GPU. The system itself also uses up some of it, meaning even less is available. So how does it manage to successfully run Qwen3.5-9B? Basically, there are three tricks.
The first trick is quantization. Most of Garlic LLM’s weights use 4-bit (Q4), while the two largest matrices in each layer are further compressed to 3-bit (Q3, about 3.5 bits including scaling factors). Combined, the model is about 4.5 GiB, saving a bit more than the roughly 4.9 GiB when everything uses 4-bit. The cache responsible for remembering conversation content is also compressed to 4-bit, further reducing memory requirements, so the context length becomes only 16K Tokens.
There are also speech recognition models at 0.33 GiB and two speech synthesis models at 0.29 GiB and 0.09 GiB, for a total of about 5.23 GiB.
Image source: Garlic LLM
The second approach is to communicate directly with the GPU. It does not use llama.cpp, which is common on PCs, nor is it a Vulkan port; instead, it bypasses the GPU driver.
The developer wrote dedicated compute kernels in OpenCL C, then compiled them via LLVM to run on the PS4’s AMD GCN architecture GPU. For each token generated, the program assembles its own PM4 command buffer. On the CPU side, it uses pure C to handle tokenization, the interface, text rendering, and audio.
The final trick is MTP speculative decoding. Qwen3.5 itself comes with a multi-token prediction (MTP) module, which can first guess up to two tokens at once and then hand them to the full model for joint verification; if the guesses are correct, it effectively produces multiple tokens at once. This setting is also the same as Alibaba’s recommendation to use 2 speculative tokens in vLLM.
Below is a table of the main features of Garlic LLM:
| Function | Special features |
|---|---|
| AI text chat | Answer questions using Qwen3.5-9B, with support for a 16K tokens context. |
| Voice conversation | Using the Chatterbox speech model, it supports voice responses in 7 languages: Spanish, English, Portuguese, Russian, Italian, French, and German. |
| Speech-to-text | Press and hold the controller button to dictate, powered by NVIDIA’s Parakeet TDT 0.6B v3, with support for 25 European languages. |
| Python mode | MicroPython programs written by AI and executed directly on PS4 |
| Think mode | Enable additional reasoning to handle more complex problems; off by default; each reasoning session takes about half a minute. |
For those interested in trying it out, note that it cannot be installed directly on a PS4; the PS4 must first have GoldHEN installed, which is a homebrew enabler for jailbroken PS4 consoles.
The developer particularly emphasizes that the App itself does not contain any crack or exploit programs; users must install GoldHEN themselves and bear the risk. The project also has no relationship whatsoever with Sony.
For installation, the integrated installer is about 5.7GB and already includes all AI models. It can be downloaded from Hugging Face; after enabling debug settings, install it via the PS4’s Package Installer. The console needs about 6GB of free space. If you first copy the installer to the console’s internal hard drive and then install it, you’ll need about 12GB. If you want to use voice features, you’ll also need a microphone that the console recognizes.
In terms of compatibility, the developer initially tested on the original and Slim PS4 with firmware 11.52, but other players have now reported successful runs, including that it also works on the PS4 Pro with firmware 9.00, 11.00, and 12.02, with a maximum speed of up to 45 tokens per second.
For those who want to play on PS5, another PS5LM is more recommended: run it directly with llama.cpp, and the speed can exceed 100 tokens per second. If running the roughly three-times-larger Qwen 27-billion-parameter model, it is about 20 tokens per second.
Source: KOCPC Chinese