
Google CEO Sundar Pichai, in the early hours of October 28 Taiwan timeAnnounce on X DeepMind unveils Genie 4, “our most realistic and interactive world model to date,” and lists four highlights: real-time control of dynamic environments (changing events, camera angles, and actions), generation of native audio synchronized with the world (from ambient sounds to characters that can converse in real time), simulation of photorealistic scenes and real physics, and leveraging Gemini’s reasoning capabilities to make multi-step events more coherent.
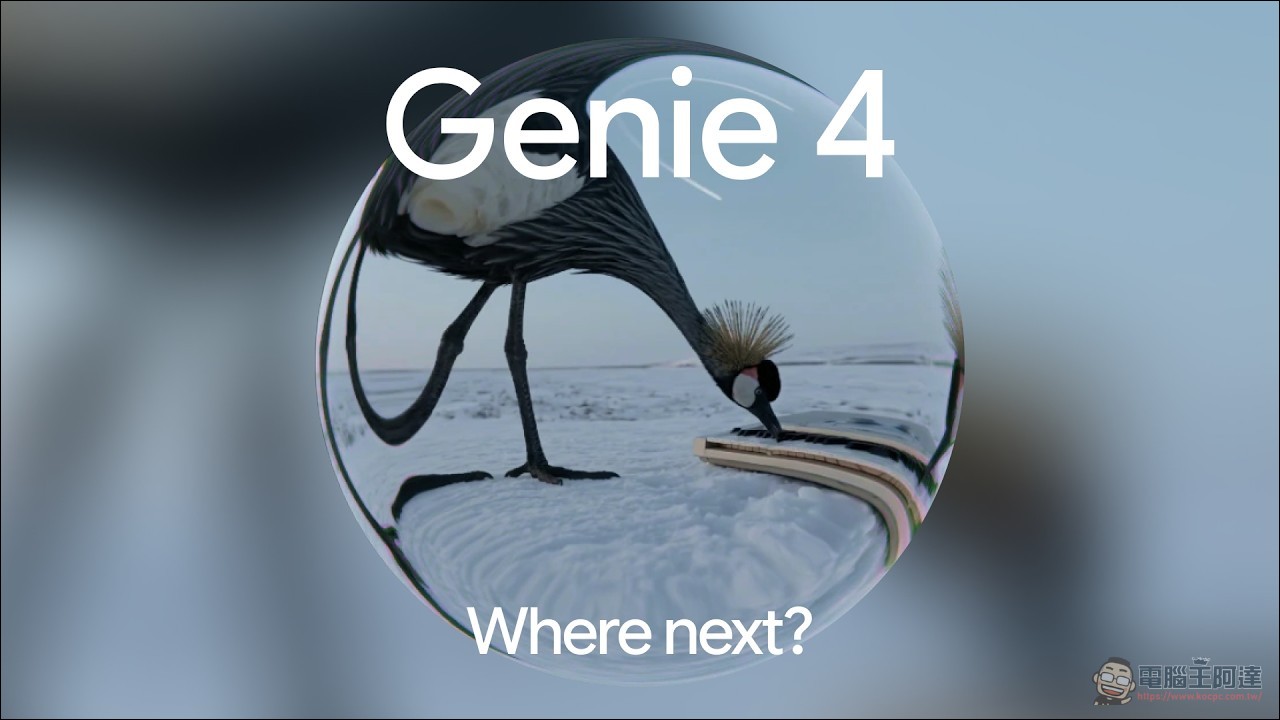
Unlike models like Sora that generate a video clip, a World Model generates an environment you can step into: there is no need to precompute the scene or write code for interactive elements; the model grows the world in real time in every frame you explore. The official model page describes Genie 4 as the “most interactive” world model to date, capable of generating photorealistic worlds you can explore, shape, and interact with from text and image prompts. DeepMind wrote on its official blog: “Understanding and simulating the world is a key part of building artificial general intelligence (AGI).”
With the Gemini family as the backbone and 3.8 Flash as the director.
Official technical documentation states that Genie 4 is natively multimodal: music, ambient noise, interactive dialogue, and the world are generated simultaneously. The model is built on the Gemini family; Gemini Omni is responsible for making the simulation closely match real-world appearance and behavior, while other Gemini models provide the complex reasoning needed to maintain scene coherence.
The most interesting design is the “director mechanism”: to achieve multi-step event reasoning in real-time generation, Gemini 3.8 Flash acts as a guiding Agent in the loop throughout. While Genie 4 generates the world, Gemini observes the scene, breaks the goal into a series of steps, and checks frame by frame whether each step is complete; when the world changes or the user intervenes, the plan is immediately rewritten. The official statement says this unlocks reliable causality, procedural behavior, and multi-step reasoning capabilities.
Four Key Capabilities and Hands-on Demonstration
All the demos released by the official team are actual operation recordings of “keyboard movement + real-time directing via text prompts”:
- Real-Time Shaping WorldUse natural language to change the weather, move the camera, or add new characters or objects at any time; Gemini contextualizes the prompts and blends them into the surrounding scene. Even when you’re not giving instructions, it keeps monitoring and advancing the world, letting the scene play out on its own.[2]
- Physics and Characters: Simulates realistic physical scenarios such as aerodynamics and collisions; according to the official self-assessment, the biggest leap is in the characters—their movements are natural, they respond organically to the environment, and they can be guided in real time.
- Native audioDeepMind’s world model has built-in sound for the first time: background ambient sounds and sound effects specified by prompts are all generated directly by the model. In the demo video, the saxophone, wind, and volcanic rumbling have no soundtrack—they are “sounds that actually exist in the scene.”
- Multi-step event: The demonstrations include complex sequences such as a UR5 robotic arm holding a dropper and dripping liquid onto a culture plate to trigger micro electric sparks, and a first-person magician waving a wand in a porcelain animal display room. There is also a 16mm documentary-style saxophonist on a lake; the prompts specify even film grain and low contrast with complete clarity. One of its official positionings is “letting AI systems test how to respond to different environments in simulation before entering the real world,” covering robot and Agent training scenarios.
To be frank about the limitations: within minutes, you “forget what the world looks like.”
Rarely, DeepMind was quite candid about the limitations this time. Genie 4 can maintain a coherent environment for a short period, but visual details and object permanence drift over time; the longer the simulation runs, the more complex prompts are changed, and the more you move around the scene, the more pronounced the drift becomes. Complex physical interactions, real-time audio accuracy, rendering of readable text, spatial precision, and long-term consistency are all still ongoing research.
On the safety side, Genie 4 has built-in safety guardrails consistent with other Google models. Before launch, it underwent rigorous internal safety evaluations to prevent the generation of harmful content, and all generated videos and audio carry SynthID invisible digital watermarks. This time, it is deliberately being released first to “trusted testers” to gather feedback before gradually expanding.
How can you touch it?
The research preview has begun rolling out to trusted testers. Next in the rollout order: Google AI Ultra subscribers (plans start at $100 per month, about NT$3,250) can use it in Project Genie, while developers and early partners can get early access through the Gemini API and Google AI Studio. API pricing has not yet been announced, and the official waitlist for Genie 4 in Project Genie is now open.
A lesson worth heeding from the previous generation: when Genie 3 was announced last August, it caused a sensation and even sent gaming stocks plunging, but it never moved beyond the limited-access experience of the Project Genie web version. This time, Genie 4 has clearly written the “opening cadence” into the script upfront: waitlist, early API access, partners—the whole pipeline is laid out.
The race for world models is underway.
Lay out the timeline: Genie 3 (August 2025) proved that interactive worlds can be generated; Genie 4 filled in three things at once: native audio, real human motion, and a Gemini reasoning director. The output of video generation models is “a clip”; the output of world models is “a place you can enter.” The former competes on image quality, while the latter competes on coherence and causality—these are two different tracks. DeepMind explicitly stated that the goal is the simulation layer of AGI, and conveniently offered two monetization directions: training environments for robots and Agents, and interactive entertainment for creators.
For Taiwanese readers, there are two most practical points to watch. First, anxiety in the gaming world will rise further, since even physics and character reactions are now generated in a modular way, but the list of limitations also makes clear that it is too early to talk about “replacing game engines”—it has not even cleared the hurdle of object permanence. Second, developers who want to get hands-on can sign up now for early access to the Gemini API, because the technology’s true quality depends on who can build the first practical product that is not just a demo video.
Source: KOCPC Chinese