
From now on, even video calls can’t be fully trusted. San Francisco AI research company Tavus has released its latest AI video model, Griffin, calling it the first model to pass a real-time video Turing test: in a one-minute real-time video blind test, 26 of 54 participants (48%) concluded that the person on the other side of the screen was real; their previous-generation system fooled only 1 participant (2.4%) in the same test. Tavus positions Griffin as a new model category: HIM (Human Interaction Model), a full-duplex video-to-video system that talks, listens, and sees at the same time.
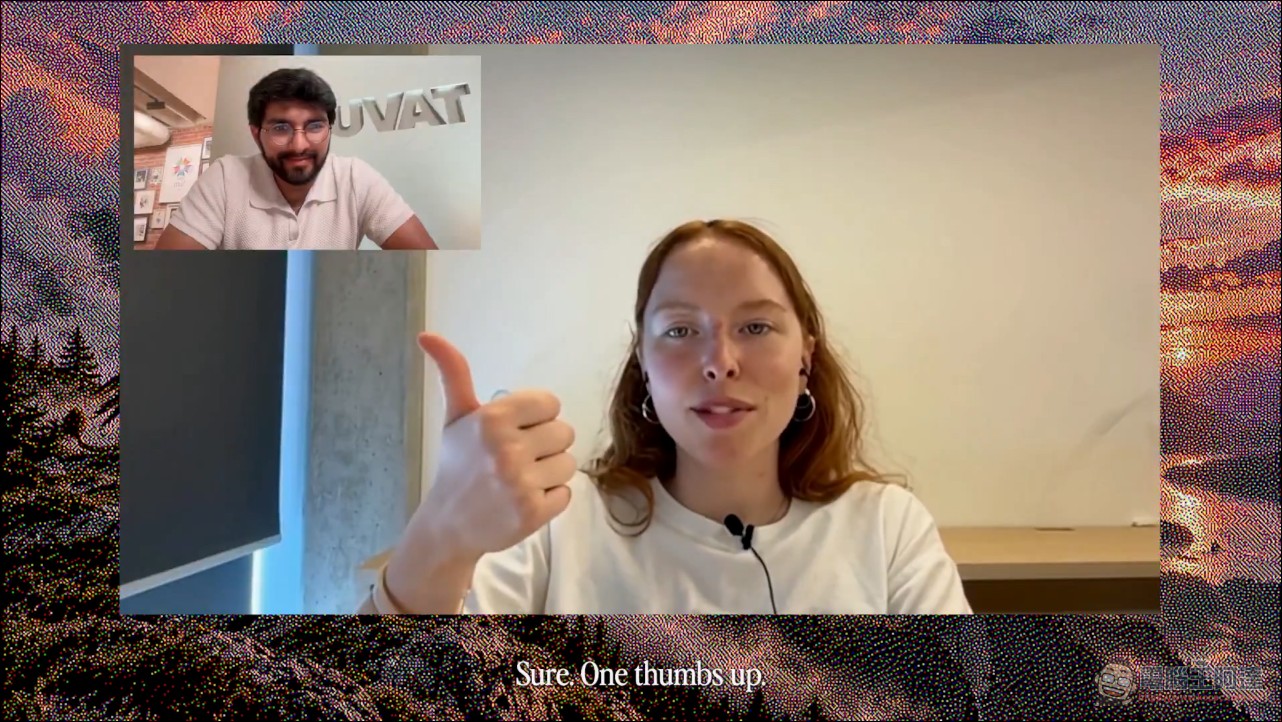
Full-duplex architecture: deciding every second whether to speak.
Most real-time voice AI systems use a cascaded pipeline: speech recognition, language model, and speech synthesis relay one after another, and they only start responding after the user has finished speaking. Griffin’s conversation engine does not operate in “turns”; instead, it continuously evaluates the conversation state at sub-second intervals, with each mini-turn deciding whether to speak, nod, emit an “uh-huh” backchannel, or stay silent. It also reads visual input, recognizing gaze, facial expressions, and objects the user holds up; pauses when a person is thinking are not treated as the end of an utterance, and when interrupted, it can stop and later pick up where it left off.
Introducing Griffin, the first model to pass the video Turing test. 48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA’s benchmark for full-duplex AI video. It’s the first Human Interaction Model (HIM). https://t.co/eb11XbC8Xr
— Tavus (@tavus) October 1, 2026
The official demo video shows the details of this capability: while playing Simon Says, Griffin has to listen to commands, watch the other person’s hands, and move its own hands at the same time; halfway through telling a story, when the other person raises a peacock puppet, it writes the peacock into the plot; when guiding a user through solving a Rubik’s Cube, it watches his hands through the camera, and when the other person is quietly thinking, it waits. The generation covers the entire frame, and the face is only one part of it: starting from one reference photo, even the shaking of the chair the person is sitting on, the shadows, and the background are all within the scope of real-time generation.
Underlying technology: 10-second voice cloning, 720p in 320-millisecond chunks.
Griffin is a two-part system. The continuous conversation modeling engine takes in audio and images and outputs control signals that determine “what to say and how to say it”; the audio-visual generation engine then turns these signals into speech and images, with perception, decision-making, and generation operating in parallel. On the speech side, it uses a convolutional autoencoder called Tavec to compress 48 kHz audio into continuous representations: one frame every 10 milliseconds, 40 values per frame, with no codebook; the decoder is fully causal, and audio packets are as small as 10 milliseconds, so speech can start playing before a sentence is finished. Speech generation uses an autoregressive diffusion model, VDiT, and with about 10 seconds of reference audio it can clone the speaker’s voice.
On the video side, a large bidirectional multi-step diffusion model is distilled into a few-step autoregressive generator in three stages: first, Distribution Matching Distillation is used to create a fast student model; then teacher forcing is used to convert it into block-by-block generation; finally, Self-Forcing training is used to keep long-duration generation from drifting. The VAE compresses the time axis by 8x, so at 25fps one latent corresponds to 320 milliseconds, enabling 720p video generation in real time. On an H100, the average latency from receiving audio to a reaction appearing on screen is 0.43 seconds, only half that of the next-fastest method.
NVIDIA benchmark: only 0.09 points worse than real humans.
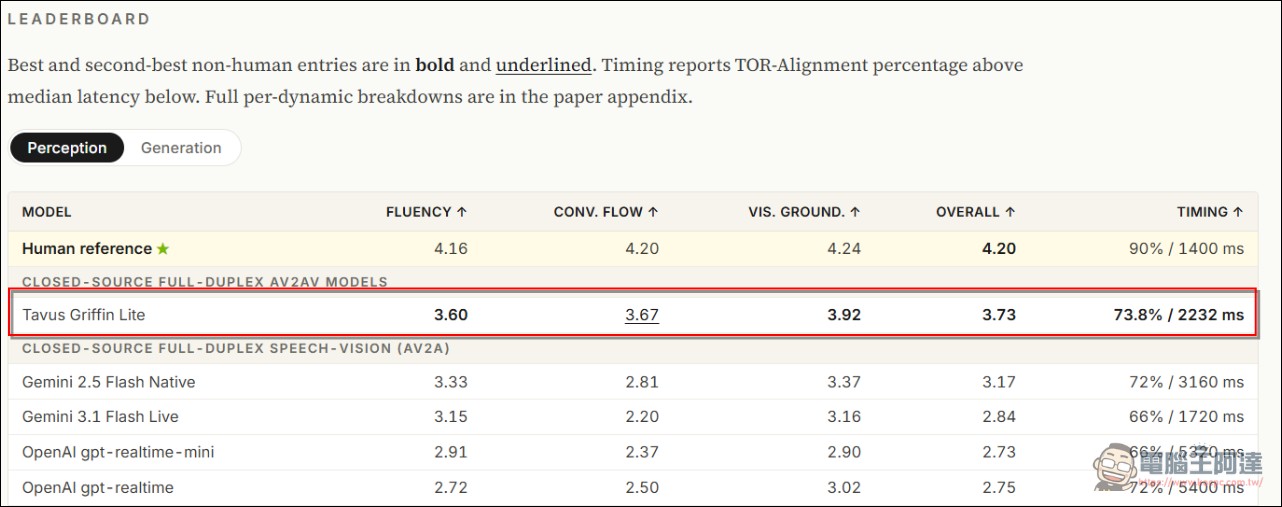
NVIDIA’s VideoFDB It is an industry benchmark for evaluating full-duplex audio-visual conversation, independently scored by NVIDIA. The generation track tests whether the model’s own generated speech and facial expressions are natural: Griffin scored 3.83 out of 5, human reference recordings scored 3.92, and the next-best system (Gemini 2.5 with Anam) scored only 2.80; Griffin’s gap from real humans narrowed to 0.09 points, more than 12 times closer to humans than any other system. The perception track tests whether the model understands the immediate situation: Griffin scored 3.73, beating MiniCPM-o 4.5’s 3.44, Gemini 2.5 Flash Native’s 3.17, and OpenAI gpt-realtime’s 2.97, making it the best at “reading the room” among the 15 models tested, with a human baseline of 4.20. The takeover-rate alignment for the two tracks (how well the timing of when to speak matches real human conversation) was 62.8% and 73.8%, respectively, both the highest on the leaderboard.
Blind test details: most doubters became suspicious within 20 seconds.
The study recruited participants through an independent research platform and told them they would have a one-minute video call with another participant to talk about what they were most looking forward to this year; the person on the other side was actually an avatar running Griffin-Lite. Only at the very end of the post-study questionnaire were they asked, “Did you ever think the other person might not be real?” and only after it ended were all participants told the truth. More than half of participants said the thought never occurred to them at any point; those who became suspicious mostly noticed within the first 20 seconds. Those who said the other party was a real participant had an average confidence of 79%, while those who said the other party was an AI had 81% confidence. On the ratings (7-point scale), naturalness was 5.4, credibility 5.6, and “willingness to chat again” 5.8; the latter was still 5.4 among participants who saw through the AI. “Felt like the other person was really listening” received 5.5, and “the conversation flowed naturally” scored 4.9, the lowest of the five items.
Why it’s not open: the company itself pressed the pause button.
Tavus has made it clear that Griffin-Lite is currently not available to customers and is only being offered to a small group of trusted testers, because the same characteristics that make it natural can also deceive people into thinking the person on the other side of the screen is not an AI. The company says it is developing safe disclosure features and working with AI safety organizations, hoping to launch the full version as soon as concerns are addressed. This risk is not hypothetical: TRM Labs found that in 2026 the annual growth rate of AI adoption by criminal organizations reached 40%, with fraud cases leading the growth. Discussion on X also focused on the same point: “48% is basically a coin flip; past this point, the only reliable way to confirm whether the other party is an AI is for it to say so itself. Disclosure is no longer optional.”
There are also reasons to question this 48%: the calls lasted only 60 seconds, the sample was 54 people, the study was conducted by the company selling the technology itself, and there has been no external replication; the definition of the “video Turing test” itself was also formulated by Tavus (in other words, by its own account). No one knows what will happen if the conversation is extended to an hour.
Conclusion: A video AI company is betting on “human-like.”
Tavus has raised about $70 million (about NT$2.24 billion) to date, with investors including CRV, Sequoia Capital, Scale Venture Partners, and Y Combinator. In November 2025, CRV led a $40 million Series B, and in 2026 it claims to serve more than 100,000 developers. Existing customers use its Phoenix, Sparrow, and Raven product line, while Griffin is its next card, putting “humanlike” front and center. Officially envisioned applications include a tutor that notices when a student does not understand and rephrases, a chat companion for older adults, and customer service that can help figure out how to repair a broken part just by having it held up. The technical numbers are impressive, but the safety mechanisms are not yet live. Griffin’s dilemma is plain: the more humanlike the model, the more it must be required to disclose that it is AI. How that gap is closed will determine whether it is a product or a source of incidents.
Source: KOCPC Chinese