
Now that local AI models have developed to this point, many people are bound to wonder: just how far have they come? Although benchmark data is available every time a new model is released, it’s just numbers after all; even a high score doesn’t guarantee that it can actually meet development needs. Recently, on the Reddit forum, there was a case that is well suited to demonstrating the current capabilities of local AI models.
A user shared that by using a single RTX 3090 to run the local Qwen3.8-27B, they spent about 5 hours and created a playable first-person zombie shooter with 3D scenes. This also means that with one person, one old card, and an open-source model—without paying any API token fees—this is now possible.
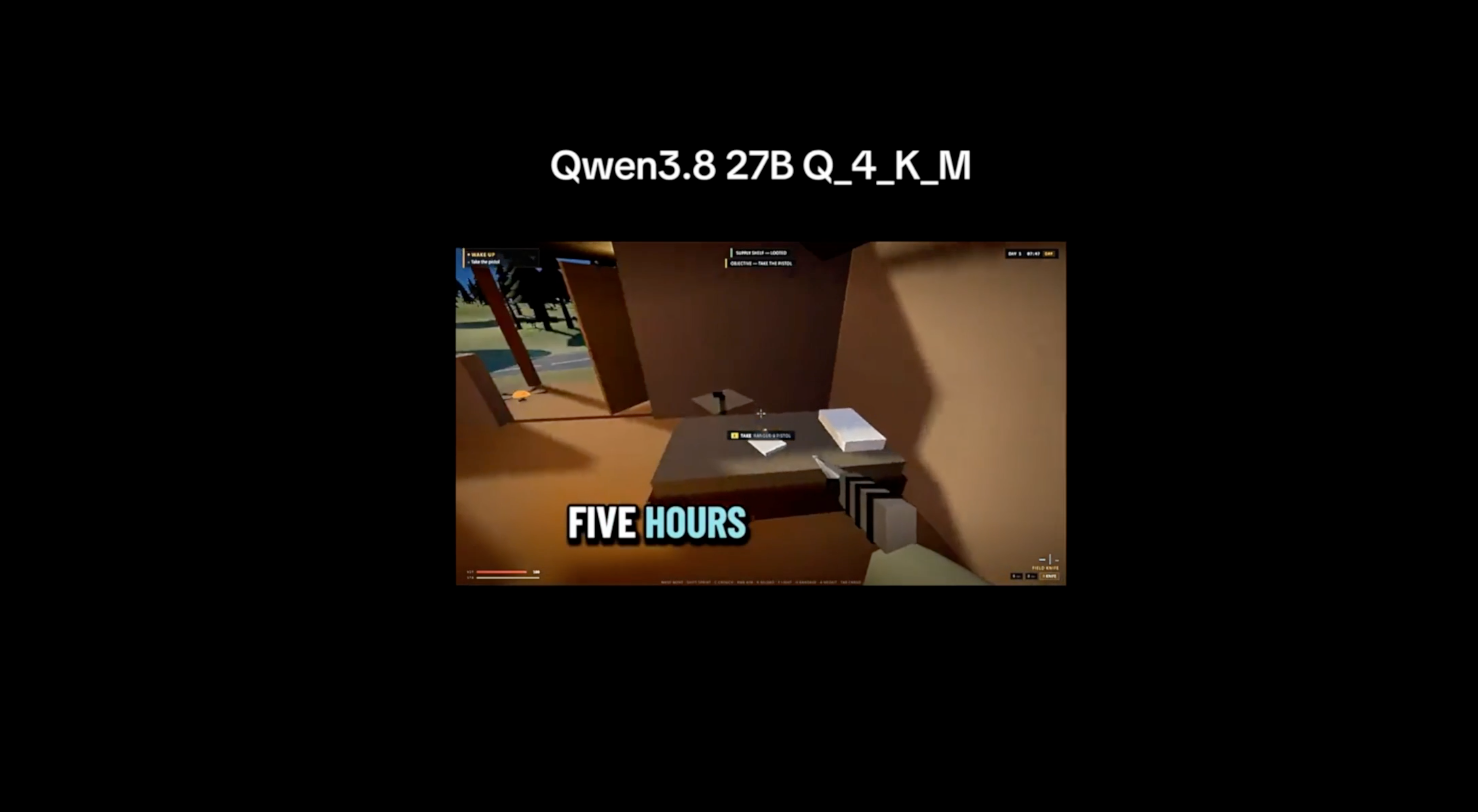
No cloud, no token burn! A netizen used a single RTX 3090 to run local Qwen3.8-27B and built a playable first-person zombie shooter in 5 hours.
A Reddit user, EcstaticDentist, recently shared on r/LocalLLaMA that on his old gaming PC with an RTX 3090, he ran the Q4KM version of Qwen3.8-27B—i.e., 4-bit quantization, with a file size of about 16.8GB—and made a first-person zombie shooter in about 5 hours. The game file is also very small, only 190MB.
整個過程大約 5 小時,用了兩套自行設定的代理式編程工具(agentic coding harness)、同一顆模型,顯卡是 RTX 3090 並且用 MSI Afterburner 超頻拉了約 12% 效能,量化版本是 Q4KM。他說這純粹是做好玩的,目的是讓大家看看「Q4KM 版 Qwen3.8-27B 效能與能力的天花板附近」做出來的專案長什麼樣,之後會把整個專案丟上 GitHub 開源,甚至邀大家「只用本機模型迭代」一起接著改。
Decided to build a game, and test the ceiling of Qwen3.8 27b
byu/EcstaticDentist inLocalLLaMA
Of course, he didn’t finish this game with just one prompt. He added in the comments that each session took about an hour, with some manual guidance interspersed along the way.
The version generated in the first round had major problems—it got stuck underneath the entire map and couldn’t move. It took several more rounds to fix player collision, movement controls, lighting and shadows one by one. He also emphasized that the entire game was “written entirely with powerful prompts,” without manually modifying any code.
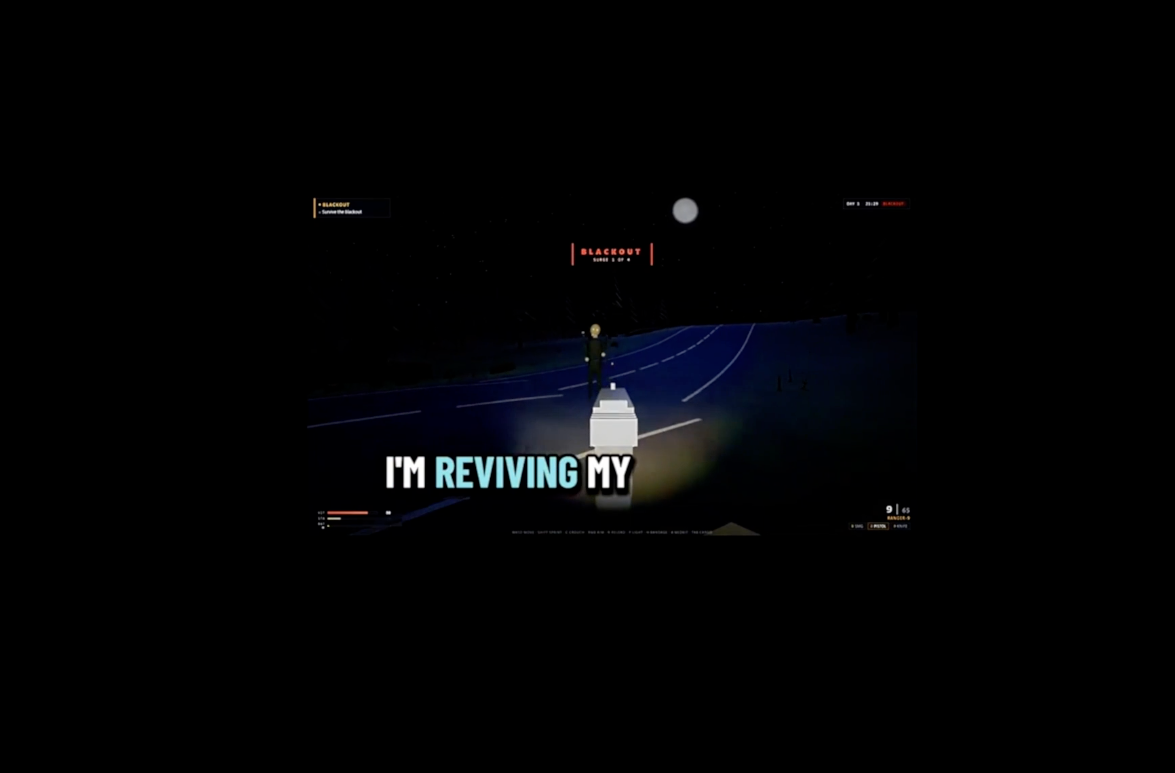
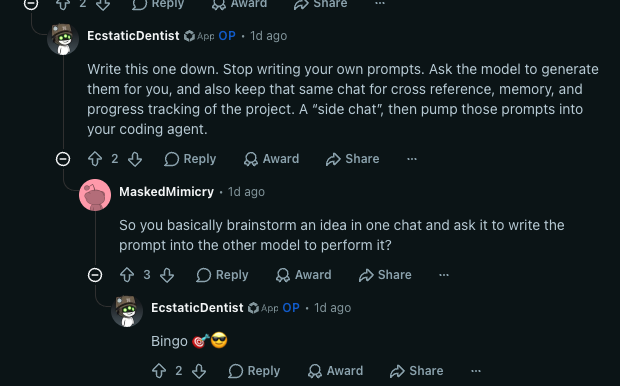
For the part about giving prompts, he also shared a tip: don’t write the prompt yourself; instead, ask the model to write it for you.
The approach is to open a separate “side conversation,” discuss what you want to do with the model there, and ask it to produce a complete prompt; this conversation can also double as the project’s memory and progress tracker. Then you hand the generated prompt to a coding agent to execute. In other words, “one conversation acts as the director, another model writes the code, and you act as the intermediary and tester.”
As for what engine or framework this game was actually made with, the original author did not specifically say. Judging from the finished product, it is speculated that it may have been built using web technologies such as HTML and JavaScript. Some netizens also believe it is very likely a JavaScript project; after all, LLMs are now quite mature at writing web code, whereas there are very few cases of them actually being used to develop Unity, Godot, or Unreal Engine projects.
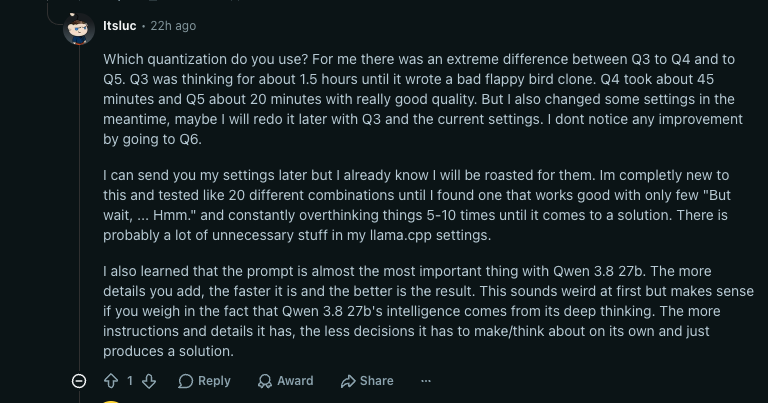
In the comments, someone also shared a hands-on test of using different quantization versions to make the same small game. The Q3 version thought for about 1.5 hours before writing a pretty bad Flappy Bird clone, Q4 took about 45 minutes, and Q5 took only 20 minutes with noticeably much better quality; with Q6, no further difference was seen. He also mentioned that Qwen3.8-27B is very sensitive to prompt details: the more complete the description, the faster it runs:
Source: KOCPC Chinese