
Normally, a PS5 shouldn’t be able to run Alibaba’s Qwen 3.8 27B model. After all, the model has 27 billion parameters, and loading it at standard 16-bit precision would take up about 54GB of memory, while the entire PS5 only has 16GB, which also has to be shared among the system, CPU, and GPU.
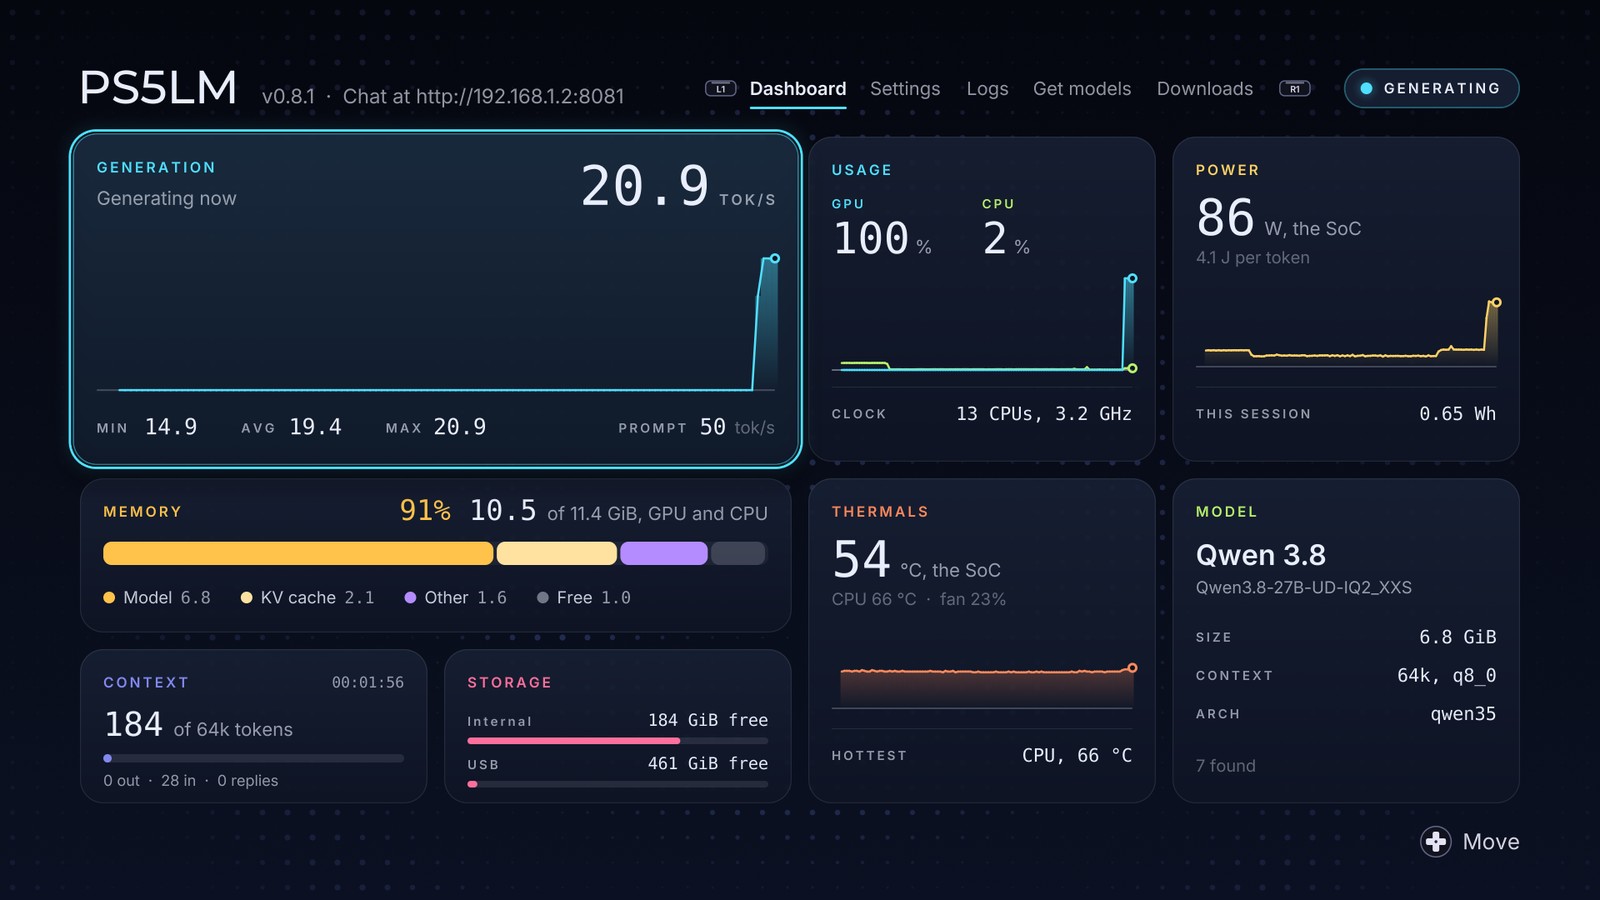
But one ingenious gamer overseas actually pulled it off: he turned a jailbroken PS5 into a local AI server and got Qwen3.8 27B running directly on the console’s GPU (a quantized version, of course), clocking an output of 20.9 tokens per second, while the small Llama 3.2 3B model even hit 124 tokens per second.
Jailbroken PS5 becomes a local AI server! It can run a 27-billion-parameter Qwen3.8, with the small model hitting 124 tokens per second.
This project is called PS5LM, and its approach is to port the open-source AI inference tool llama.cpp to a jailbroken PS5. Recently, on the Reddit r/LocalLLM subreddit, a user named AdIllustrious7246 shared his test results.
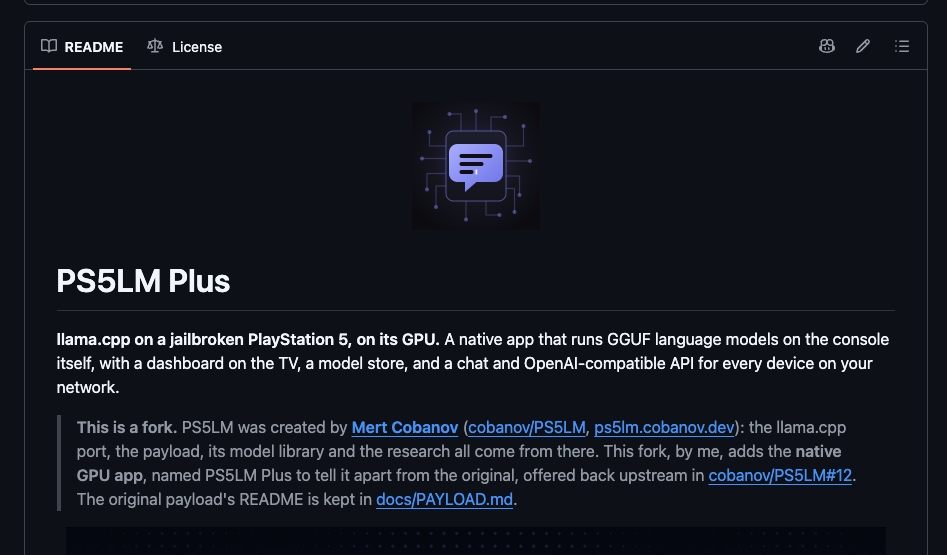
A few weeks ago, he saw another user metover share the PS5LM project, found it very interesting, so he forked it and made some modifications, and ultimately succeeded in building this version that can run large models on the PS5 GPU.
Qwen 27B at ~20 tok/s on a jailbroken PS5's GPU. I forked PS5LM and turned it into a native app
byu/AdIllustrious7246 inLocalLLM
Although the original PS5LM project had already successfully ported the AI inference tool llama.cpp to the jailbroken PS5, it initially used a payload (a small program loaded and executed after jailbreaking), relying mainly on the CPU for AI computation. Because this execution method was subject to memory allocation limits and could use at most about 6GB of memory, it was only suitable for running AI models with a relatively small number of parameters.
This time, his modification directly turned llama.cpp into a native PS5 application and used Vulkan and the RADV driver to let the GPU handle AI inference, breaking past the original memory limit and increasing available memory from about 6GB to 11.4GB, ultimately enabling it to successfully run the Qwen3.8 27B model.
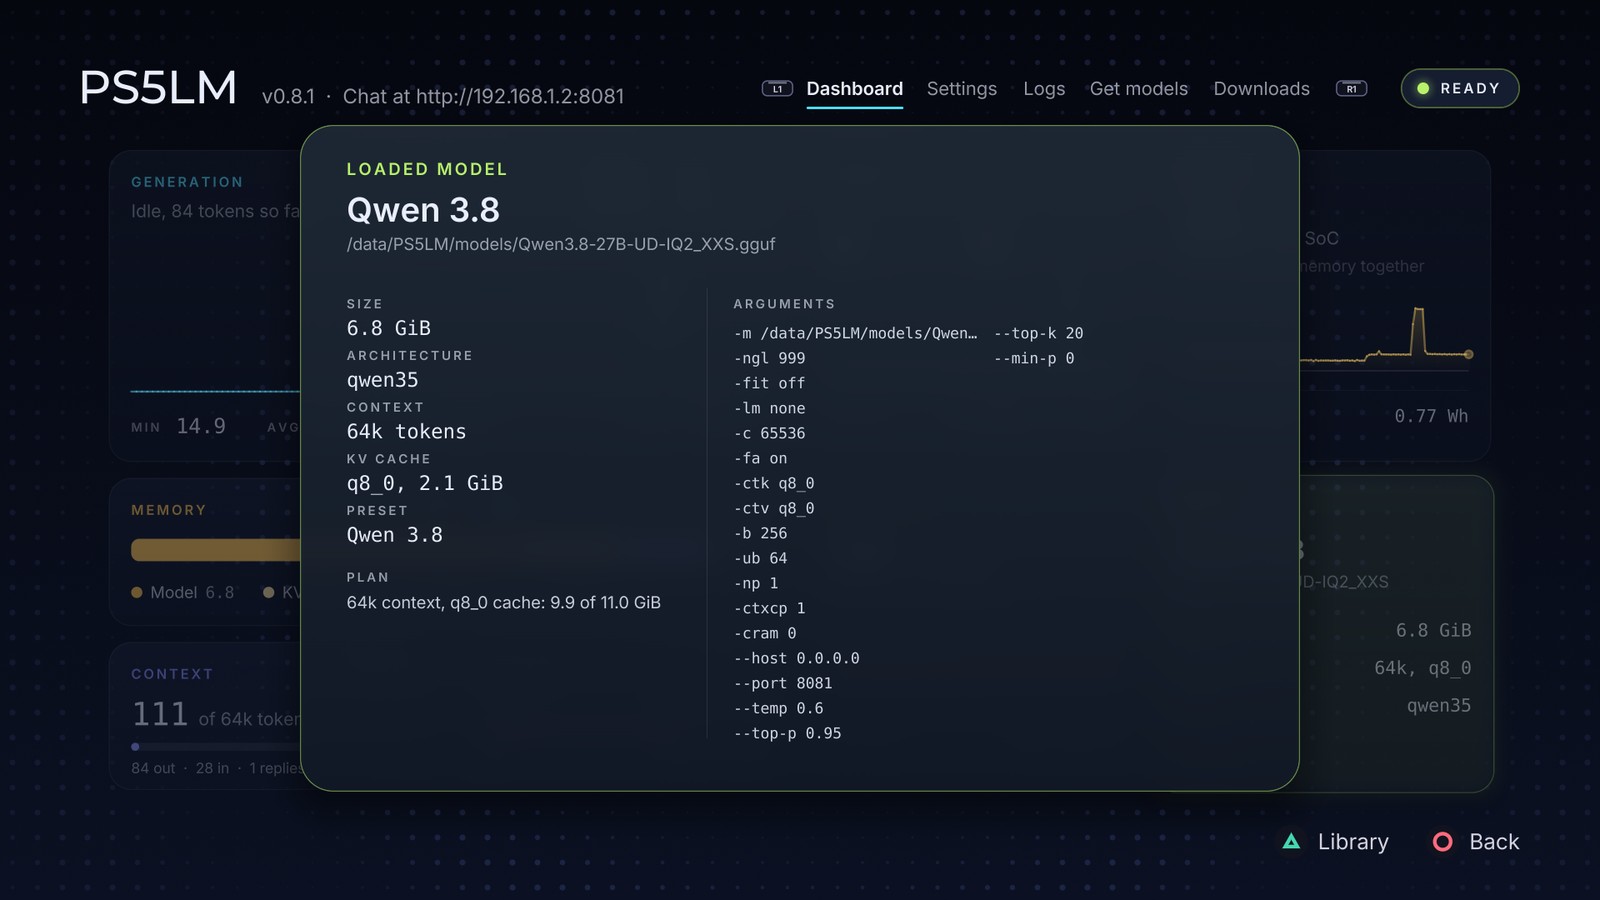
However, the regular 16-bit precision version of Qwen3.8 27B requires about 54GB of memory just for the model weights, and 11.4GB is still far from enough, so what runs is naturally the quantized version. The heavily quantized IQ2_XXS compresses the model weights to about 6.8GB, allowing it to finally load and run successfully. He also shared on GitHub the revised “PS5LM Plus」。
It works somewhat similarly to Ollama on a computer. Just install and launch PS5LM Plus on a jailbroken PS5, and you can browse the model library through the interface, searching for and downloading the AI models you want directly from Hugging Face, without having to download them on a computer first and transfer them to the PS5. You can also use the DualSense controller to select models during operation, and the system will pre-determine whether a model can run under the PS5’s memory limitations.
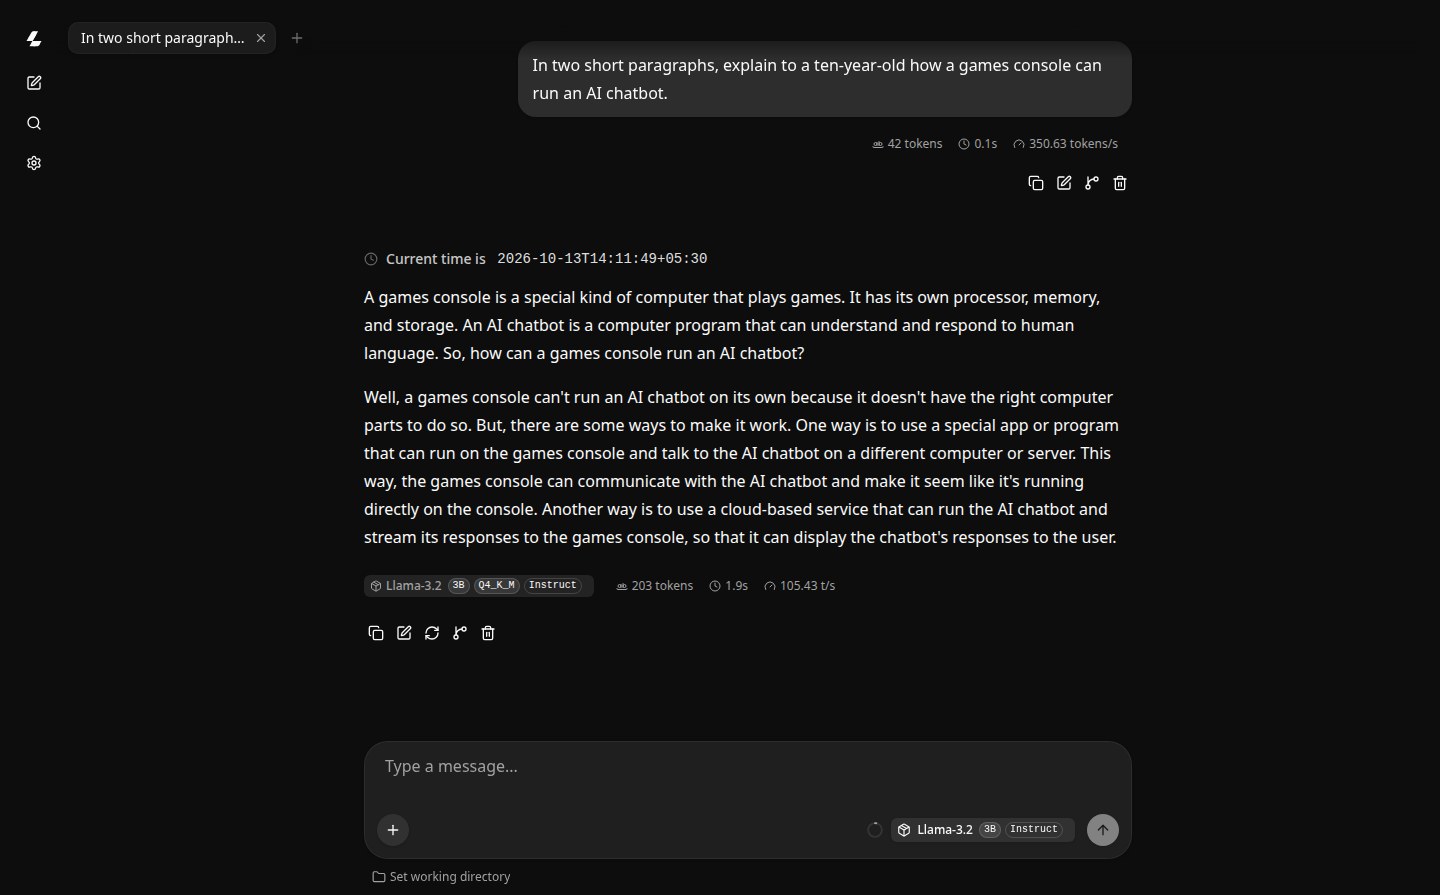
To chat with the AI, use another device—a phone or computer on the same network—and connect to the host’s IP through a browser to open llama.cpp’s built-in chat interface. It also supports an OpenAI-compatible API, meaning other AI tools that support custom API endpoints can directly call the model running on the PS5:
After the model loads, the screen displays a real-time dashboard that includes tokens per second, GPU and CPU usage, power draw, temperature, and fan status, as well as how much memory is used by the model and the conversation cache respectively:
In terms of testing, besides the three models mentioned in the Reddit post, he also tested the higher-quality Qwen3.8 27B UD-Q2_K_XL version, with a file size of 9.15GiB and a context of 32K:
| model | File size | Context | Tokens per second |
|---|---|---|---|
| Qwen3.8 27B(UD-IQ2_XXS) | 6.77GiB | 64K | 20.7–20.9 |
| Qwen3.8 27B(UD-Q2_K_XL) | 9.15GiB | 32K | 20.3 |
| Gemma 4 E4B(q4_0) | 4.8GiB | 64K | 61 |
| Llama 3.2 3B(Q4_K_M) | 1.9GiB | 64K | 124 |
Source: KOCPC Chinese